In this chapter, we will introduce the endpoint of traditional ML, the cornerstone of DL (Deep Learning), and the foundation of LLMs—Transformers.
I believe that after finishing this chapter, we will not be far from LLMs.
Compared to the native Transformers, its advanced wrapper, Keras, is much easier to use and more suitable for beginners, especially for those who do not have a good foundation in mathematics and theory. We will also use Keras in this large chapter.
The content of this chapter is indeed too much, so it is divided into 4 small chapters, which means 4 articles to introduce them separately.
By the way, I personally think that the original paper on Transformers, 'Attention Is All You Need', is a very worthwhile paper to study. However, before reading that paper, allow me to explain it so that it won't feel so unfamiliar when you read it.
Next, we have two branches, one leaning towards the language output type of LLM direction, and the other is the Computer Vision direction, which is what I am currently researching. If you think you want to understand the LLM direction more, you can read the later categorized specialized articles, starting from Labels. If you think you prefer CV, we will start from PyTorch.
Let's start from the beginning. This chapter is the most basic and also the most important Attention mechanism.
First, we need to answer a few questions:
Why do we use theAttention mechanism?
Here I will directly quote a passage from AI:
Before Attention appeared, RNN/LSTM had slow serial training speeds and struggled to remember information that was far apart in long texts. Attention allows each token to directly associate with words at any position in the entire text, capturing long-distance dependencies and supporting parallel computation, fully utilizing GPU computing power, making it possible to train large language models.
What is the Attention mechanism used for?
We know that it is difficult to understand the meaning of a word in context by itself. For example, in the sentence 'Apple Company Invented Phones', if we only see 'Apple', you might think of the fruit, but considering the context, we know that 'apple' in this sentence refers to the tech company that invented phones.
Let's start with vectors.
Before discussing the index Q, let's clarify what vectors are in the context of ML.
----------------------------------------------------------------------------------------------------------------------------
First, when we classify each word, we will give it a (generally) three-dimensional vector.
For example: King = { 14, 56, 38 }. male = { 8, 34, 25 } (this is fake, I don't know what it is)
So why do we need to give each word an index? The reason is that we need a quantity that can relate all words together. Vectors solve this problem well.
Just like the distance of vectors, the closer the distance between the labeled vectors of two words, the higher the relationship between the two words in reality.
Generally speaking, for most cases, there is a very interesting fact:
When we subtract the vector of Male from the vector of King (which I just made up), we will get the vector of Queen. Think about it, in terms of real logic, when we subtract all male kings from all kings, don't we get the set of queens? Hey, this is the role of vectors.
Now that we understand the role of vectors in word embeddings, we can conveniently discuss Q, K, and V.
Let's start with Q. What is Q? Q here stands for 'Query', which is an index.
Q represents where we want to look.
What about K? K stands for Key, which is a feature label.
What does that mean? For example, if our input token is 'apple', then its Key is fruit/company.
And V? V stands for Value, which is the core information carried by this token.
This refers to the deeper information carried by this token, such as social attributes, functions, etc.Advanceddata.
Having understood what these three letters are, we need to process this token.
Let's assume the word vector that this word carries is X_a.
Here, each W represents a weight, which is the weight information learned by the model during training.
Let's assume we input '苹果公司发明了手机'.
In English, that is 'Apple Company invented phones'.
\(Q_a = X_a * W_Q K_a = X_a * W_L V_a = X_a * W_V\)Thus, we have obtained the values of the Q, K, and V vectors.
Alright, next, let's process these three values.
We take the Q value of the word 'apple' and perform a dot product with all the K values of this sentence to get the correlation between the two tokens (all values below are fictional).
Q_A · Ka = 3.2 (itself, high correlation)
Q_A · Kc = 1.4 (apple is a company, relatively high correlation)
Q_A · Ki = 9.6 (there is a subject-verb relationship between the two words, very high correlation)
Q_A · Kp = 2.2 (the two words have a subject-object relationship, high correlation)
Next, we divide these obtained values by the square root of Dk (Dk is the vector dimension) (Softmax normalization).
If Dk is very large, then the resulting values will be very large, and the model will not be able to train.
The purpose of dividing like this is to make the model trainable. To cool down the data.
After cooling down the values, we do one thing:Normalization
What does this do? It encodes the values after Softmax into a range between 0 and 1, where all values add up to 1.
At this point, we have obtained what is calledWeights.
Apple - Apple = 0.3
Apple - Company = 0.05
Apple - Invented = 0.5
Apple - phone = 0.15
At this time, V comes into play. We sum up all the V values of this sentence, and we get the information carried by the word Apple.
\(Attention = 0.3 * V_a + 0.05 * V_c + 0.5 * V_I + 0.15* V_p\)To summarize into a formula, it looks like this:
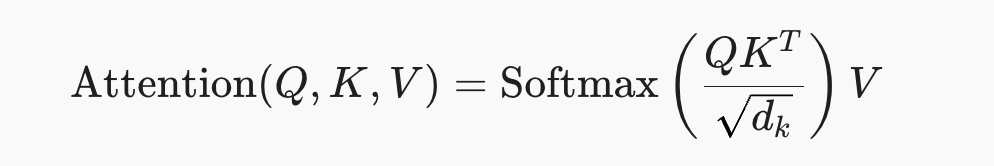
By now, you have understood the Attention mechanism.
Don't rush, we are not done yet. Here, we might wonder, the weight of 'Invented' is as high as 0.5, does that mean the importance of other features has been diluted? Indeed it has. So in 'Attention Is All You Need', they inventedMulti-Head Attention mechanism.
The principle is as follows: we prepare H groups (usually 8-16 groups) of Wa, Wi, Wc, Wp, and perform parallel computations. For example, one group of Wp specifically observes the relationship between the subject and the object, while one group of Wi specifically observes the subject-verb relationship.
In this way, we combine the results of all groups, called(Concat),The result obtained gives us a new and more comprehensive understanding of this word.
On another note, previously we mentioned that we put all this stuff together for parallel computation, but there is a problem: how does the machine distinguish the order? For example, the machine might confuse 'Zhang San hits Li Si' with 'Li Si hits Zhang San'. Wouldn't that be chaotic? Thus, we introducePositional Encoding.
So, before we throw that chunk into parallel computation, we add a positional encoding to each word (usually generated by sine/cosine), so it won't get mixed up.
Alright, that's all about Attention. In the next issue, we will introduce Encoder and Decoder.
Thank you so much for reading this far~ Goodbye~